Different inputs. Consistent data. Readable by any AI.
FeedGPT receives your feeds by webhook and shapes every record with a reusable data template. Bring several inputs into one source, map each provider's format once, and the result is ready for Claude, ChatGPT or your own agent over MCP, or for anything that calls the API.
// works with Claude, ChatGPT, and any MCP-compatible client

- externalId
- Bright Datapost_id: "1080000000000001"ApifypostId: "1080000000000001"
- content
- Bright Datacontent: "Behind the counter at 5am: how ou…"Apifytext: "Behind the counter at 5am: how ou…"
- publishedAt
- Bright Datadate_posted: "2026-03-12T05:40:00.000Z"Apifytime: "2026-03-12T05:40:00.000Z"
- metrics.likes
- Bright Datalikes: 412Apifylikes: 412
- metrics.comments
- Bright Datanum_comments: 37Apifycomments: 37
- metrics.views
- Bright Datavideo_view_count: 12650ApifyvideoPostViewCount: 12647
- metrics.plays
- Bright Dataplay_count: 23410ApifyviewsCount: 23402
| Field | Bright Data sends | Apify sends |
|---|---|---|
| externalId | post_id: "1080000000000001" | postId: "1080000000000001" |
| content | content: "Behind the counter at 5am: how ou…" | text: "Behind the counter at 5am: how ou…" |
| publishedAt | date_posted: "2026-03-12T05:40:00.000Z" | time: "2026-03-12T05:40:00.000Z" |
| metrics.likes | likes: 412 | likes: 412 |
| metrics.comments | num_comments: 37 | comments: 37 |
| metrics.views | video_view_count: 12650 | videoPostViewCount: 12647 |
| metrics.plays | play_count: 23410 | viewsCount: 23402 |
Start with a template. Make it yours.
A template defines the fields once and, per input, where each one comes from in a provider's payload. Every source starts from one and keeps its own copy, so a template update is something you choose, never something that happens to you.
Data template
Reuse the fields and the mappings instead of starting from scratch. Eight starters ship built in; your own are published from the playground.
Multi-input source
Bring several inputs into one source and keep one consistent output. Each input has its own webhook URL and its own mapping.
Variants
Support different incoming formats of the same platform, Bright Data’s and Apify’s say, with a mapping suited to each.

Choose a template. Connect your inputs. Use consistent data.
You set a source up once. The questions get asked in Claude, ChatGPT or your own agent, not in another interface to learn.
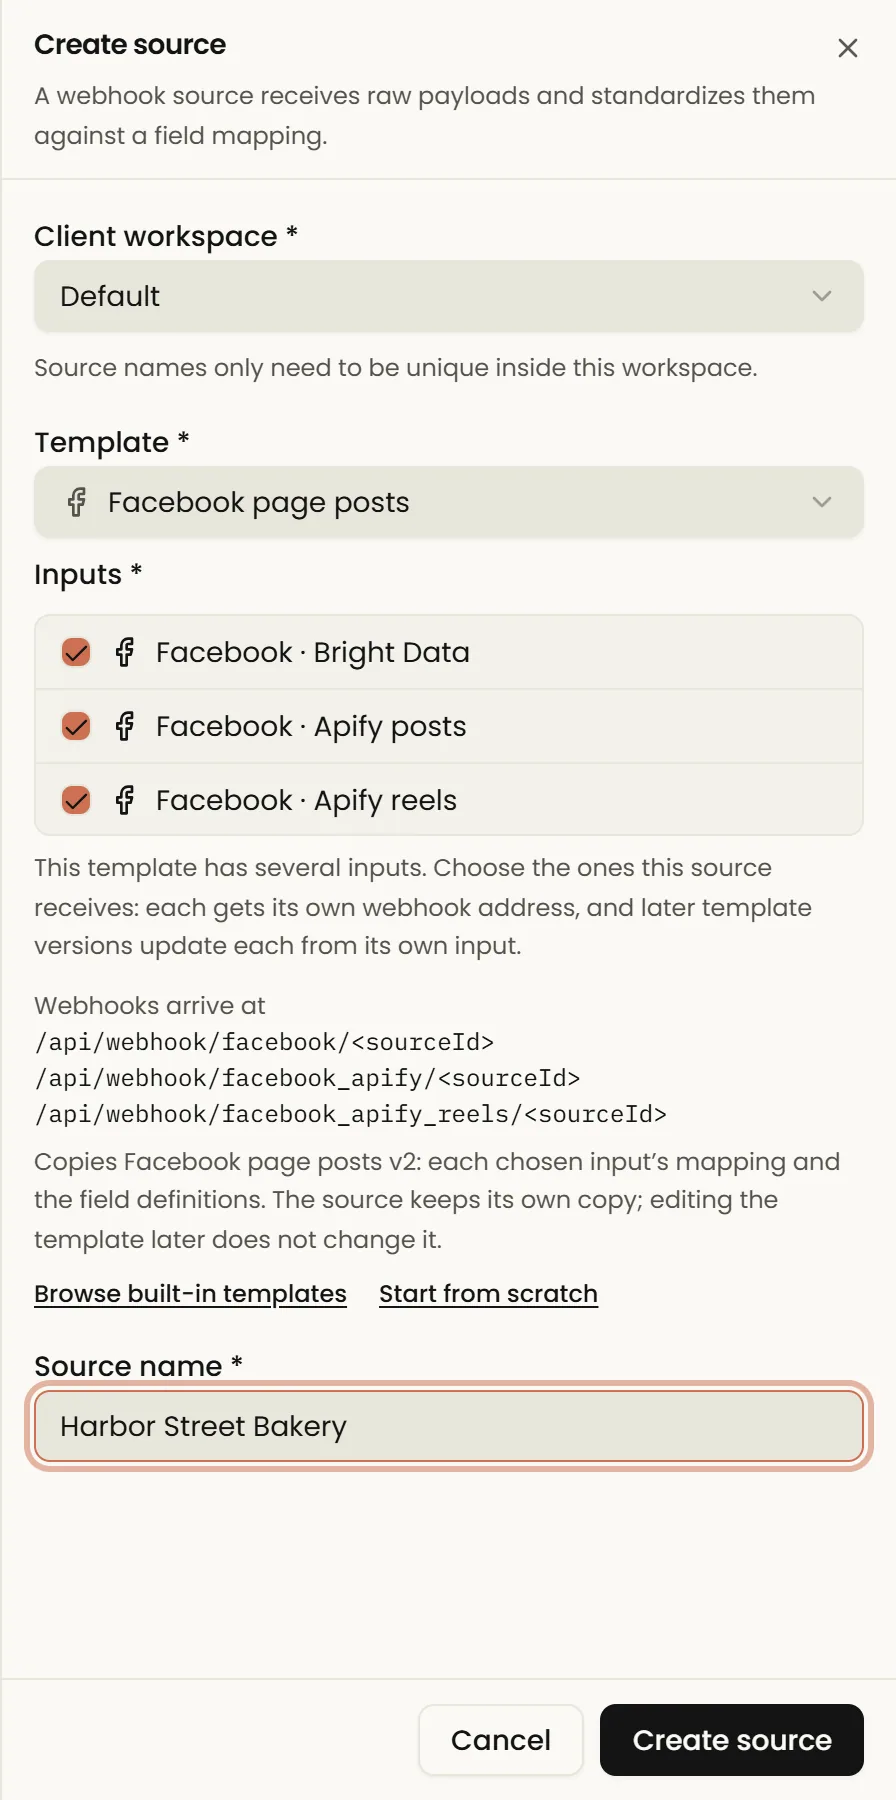
Choose a template
Pick the template built for the payload your provider sends and tick the inputs this source will receive. Each input gets its own webhook URL, so a Bright Data run and an Apify actor can feed one source.
Connect your inputs
Point n8n, Zapier, Make, a scraper run or your own script at those URLs: anything that can POST JSON. Each input’s mapping turns its format into one record shape, a post two providers both deliver is stored once, and every extraction is logged.

Use consistent data
Connect the FeedGPT MCP server to Claude, ChatGPT or your own agent, or read the REST API. Every record has the same fields whichever input delivered it, so the question can be about the client rather than the scraper.

Switch scrapers, keep your columns.
A template defines what each field means once. Each input says where that field comes from in its provider's payload, or that it does not apply there. So a Bright Data feed and an Apify feed land in the same columns, a field a provider never sends is not counted against it, and a gap is reported as a gap rather than guessed.

| Field | Bright Data | Apify posts | Apify reels |
|---|---|---|---|
| content | 3/4 | 2/2 | 2/2 |
| url | 4/4 | 2/2 | 2/2 |
| publishedAt | 4/4 | 2/2 | 2/2 |
| author. | 4/4 | 2/2 | 2/2 |
| author. | 4/4 | 2/2 | 2/2 |
| author. | 4/4 | 2/2 | n/a |
| hashtags | 2/4 | n/a | n/a |
| metrics. | 4/4 | 2/2 | n/a |
| metrics. | 4/4 | 2/2 | n/a |
| metrics. | 4/4 | 2/2 | n/a |
| metrics. | 2/4 | 1/2 | n/a |
| metrics. | 1/4 | 1/2 | 2/2 |
| postType | 3/4 | n/a | n/a |

Works with what you already automate with.
Each input's webhook URL is a standard HTTP target. If your tool can send a POST request, it can feed FeedGPT; nothing here pulls from a platform on your behalf.
Because we can't control what shape of payload an automation tool sends, schema healing isn't a nice-to-have here — it's what makes "connect anything" safe to promise.
Ask in the assistant you already use.
Connect Claude, ChatGPT or your own agent to the FeedGPT MCP server with OAuth or an API key, or call the REST API from a script or an automation. The same records, the same fields, whichever input delivered them. An agent can read your data, and it can also create sources, inspect schemas and apply the repairs you approve, each operation governed by a permission the owner can revoke per key.
Reads
15Scoped to the key's workspaces. No permission narrows them.
- describe_fields
- get_field_mapping
- get_posts_page
- get_template
- get_template_draft
- list_mapping_proposals
- list_post_audit_logs
- list_reprocess_runs
- list_schema_audit_logs
- list_sources
- list_templates
- list_workspaces
- preview_mapping_proposal
- test_field_mapping
- test_template_draft
Operations
17Each governed by a permission an owner can revoke per key.
- add_source_input
- apply_mapping_proposal
- archive_source_input
- copy_template
- create_source
- create_template
- dismiss_mapping_proposal
- ingest_record
- inspect_schema
- publish_template
- reprocess_posts
- reset_demo_data
- restore_source_input
- save_template_draft
- simulate_webhook_ingest
- update_field_mapping
- upgrade_source_template
Every field extraction has a paper trail.
Providers change their payload shapes without warning. FeedGPT is built to notice, propose a fix, and show its work, not to fail silently.

Confidence-gated healing
When a payload carries a path no mapping knows, FeedGPT proposes a field for it and scores the proposal against the payloads it has actually seen. Above your threshold it can apply itself; below it, it waits for review. Nothing is guessed silently, and a Dry Run shows what applying would change before anything is written.
Trace any number back to its source
Every ingestion, healing decision, mapping edit and reprocess run is logged with who or what made it and what changed. A value that could not be extracted stays null rather than becoming a guess, so "why does this say 42 likes" always has a real answer.
Roadmap: schema-healing inference moving to infrastructure we control (via the NVIDIA Inception Program), so payload diagnosis never has to leave our own environment. This is separate from the AI you connect over MCP to analyze your data — that's still your Claude or ChatGPT, on your terms.
What agencies ask their AI — once their data is clean.
Copy any prompt, paste it into Claude, run it against Demo mode. No configuration.
Monday portfolio review
→ Replaces every dashboard login with one question.
Content diagnosis
→ Finds the high-share content your likes-sorted dashboard buries.
Reports on demand
→ Same prompt monthly, same quality from every account manager.
Upsell detector
→ Your best client becomes the sales deck for the rest.
Audience research
→ Evidence-based creative briefs instead of intuition.
The QA gate
audit trail→ Every answer backed by FeedGPT's audit trail. Show clients the log behind their report.
Run all six right now
Demo mode gives you a sample agency portfolio (three clients, six months of data) the moment you sign up. Free tier, no card.
For agencies and regulated teams who get asked to prove their numbers.
Data you can defend
Agencies and regulated teams don't get to say "the dashboard looked right." FeedGPT keeps the evidence: what came in, what changed, and why.
Recognized by the NVIDIA Inception Program and INSEAD AI Venture Lab for the underlying data-infrastructure approach.
- ✓Every extraction logged with confidence + reasoning
- ✓Malformed input rejected, not silently ingested
- ✓Duplicate detection across every source
- ✓No data leaves your control to reach the AI — MCP connects your existing assistant directly
Pay for data infrastructure. Bring your own AI.
No per-seat chatbot license — you already pay for Claude or ChatGPT. FeedGPT prices on the sources you connect.
- ✓1 source
- ✓1 workspace
- ✓Webhook and MCP ingestion
- ✓Any AI client over MCP or REST
- ✓Community support
- ✓5 sources
- ✓3 workspaces
- ✓Everything in Free
- ✓Email support
- ✓25 sources
- ✓Unlimited workspaces
- ✓Everything in Starter
- ✓Priority support
- ✓Unlimited sources
- ✓Unlimited workspaces
- ✓Everything in Growth
- ✓Uptime SLA by agreement
- ✓Dedicated support
Every plan ingests by webhook (Zapier, Make, Apify, your own cron) or from a connected agent over MCP, tracks schema drift and reprocesses records. Ingestion volume is not metered or capped, so no source ever silently stops ingesting; API usage is recorded and shown on your billing page.
Give your AI something real to read.
Connect a source, point Claude or ChatGPT at the MCP server, and ask your first question.